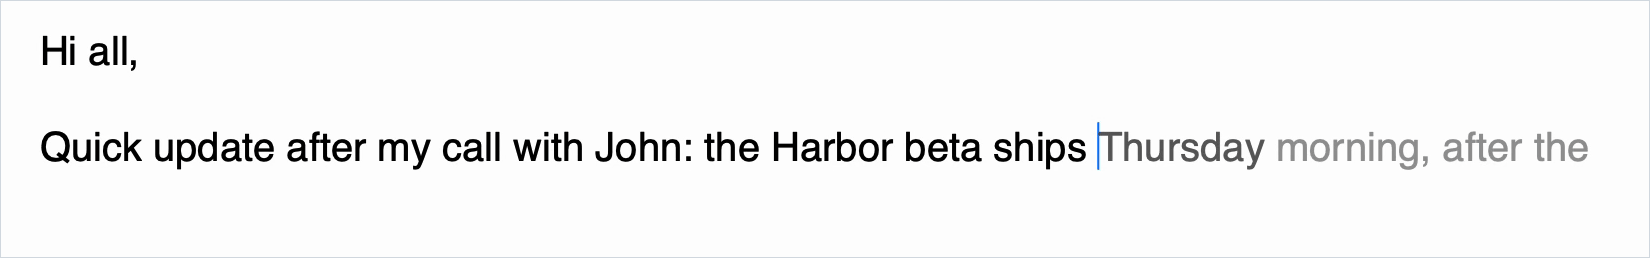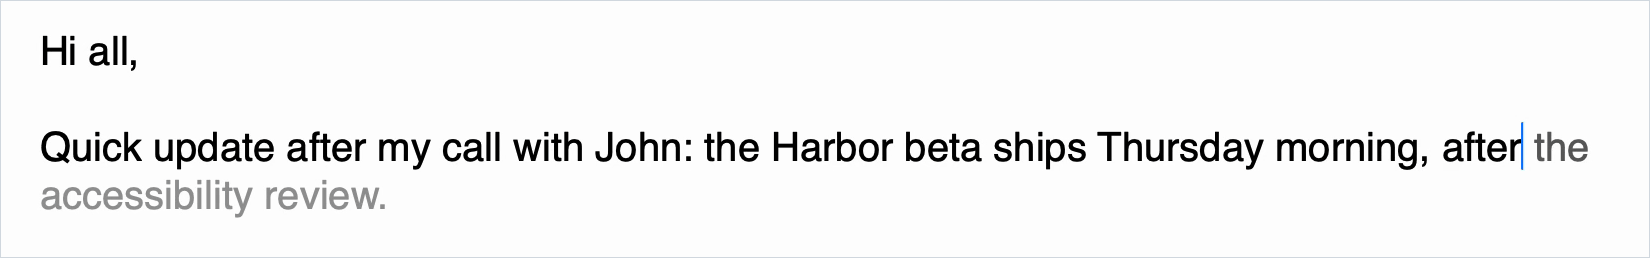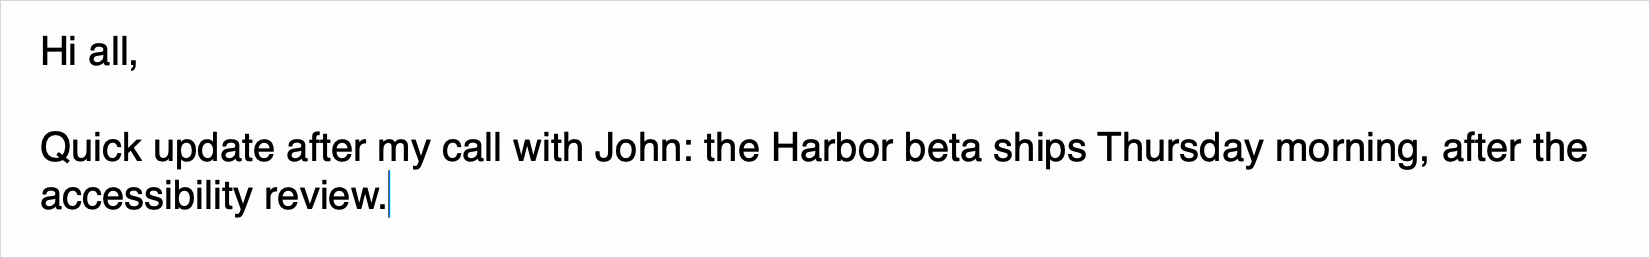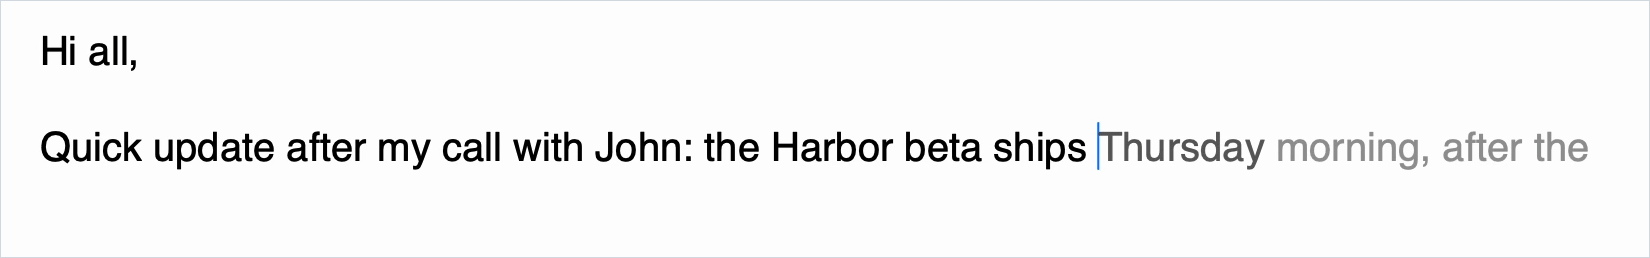
Fast enough to stay out of the way
Getting autocomplete to be useful without being intrusive or laggy took a lot of experiments with different models and quantizations. The best balance of suggestion quality and latency on a regular MacBook turned out to be the Gemma 4 E2B base model at 6-bit (Q6_K), running in-process through llama.cpp. On an M4 Max a suggestion takes a median of 56 ms while typing (see the full engine benchmark).
Update, November 19, 2026 — first suggestion after a pause: Cotypist highlights staying fast when you resume typing after a break. Previously, once llama.cpp's 180-second Metal residency keep-alive lapsed, LokalBot's first suggestion after a 5-minute pause took 95–130 ms. LokalBot now warms the loaded runtime with a single throwaway token on screen wake, unlock, click, or the first keystroke—removing that token afterward so the cached prompt stays intact—cutting a 5-minute pause down to 49–53 ms against a 47–49 ms warm reference (benchmark report; 30-minute pauses under heavy memory pressure remain unmeasured).
Context from your own work
- The text above the field. On by default, read through macOS accessibility. Private browser windows are never read.
- Your meetings, if you opt in. When your draft names something distinctive, LokalBot can add up to two facts from your own meeting notes to the model's context.
Autocomplete lives in the same app as meetings, dictation, and screen recall, which share one memory budget for their models.
How it compares
Cotypist and Cotabby are the closest local-first alternatives. As described on their sites (checked October 13, 2026; LokalBot column updated November 19, 2026):
| Feature | Cotypist | Cotabby | LokalBot |
|---|---|---|---|
| License and price | Proprietary; free for 100 words a day, paid for unlimited | AGPL-3.0, free (beta) | GPLv3, free, no limits |
| Platforms | macOS | macOS | macOS (Swift), Windows & Linux (Rust + GPUI) |
| Model | Local (Gemma 4 E4B recommended) | Local GGUF through llama.cpp, or Apple Intelligence | Gemma 4 E2B base Q6_K (Balanced) or LFM2.5 1.2B (Lightweight), in-process llama.cpp |
| First suggestion after a 5-min pause | Advertised fast resume | Not published | 49–53 ms on M4 Max (warm-up on wake, click, or key) |
| Knows what was said in your meetings | No | No | Yes, opt-in |
| Text above the field | Not documented on its site | OCR of the window | Accessibility text, never from private windows |
| Also in the app | Autocomplete only | Emoji, macros, autocorrect | Meetings, dictation, screen recall, read-only MCP |
A head-to-head with Cotabby used identical inputs and the same Gemma 4 E2B weights over 782 next-word checkpoints. LokalBot predicted the exact next word 32.7% of the time (256 of 782) and Cotabby 30.7% (240 of 782), a difference of 2.0 points with a 95% interval of 0.0 to 4.0. In other words, the two are comparable on accuracy; the work now is on the experience around the suggestions.
Try it
Turn on Autocomplete in Settings → Writing. It needs the Accessibility and Input Monitoring permissions and a one-time model download. Tab accepts a word. Password fields and apps you exclude are never read.